Grounded information access
Help teams find and summarize approved internal information with sources and access controls.
AI custom software development
Move beyond a disconnected chatbot experiment. Build an AI-enabled application around the documents, decisions, systems, and review responsibilities involved in real work.
We begin by asking where AI is useful, where deterministic software is safer, and where a person must remain responsible for the final decision.
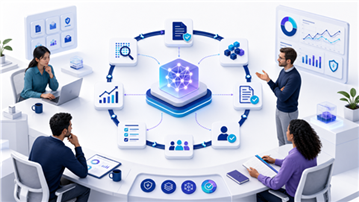
Where custom AI can fit
A strong opportunity has useful source data, a reviewable output, a clear user, and a way to measure whether the result is good enough for the task.
Help teams find and summarize approved internal information with sources and access controls.
Classify, extract, route, and flag documents while making exceptions visible for review.
Prepare context or recommendations for a responsible person rather than hiding judgment inside automation.
Responsible product boundaries
Define which data can be used, who can retrieve it, and what must stay outside the AI workflow.
Build task-specific test cases and review failure patterns before expanding use.
Make low-confidence, sensitive, or exceptional cases easy to route to a person.
Review quality, cost, latency, model changes, and user feedback as the workflow evolves.
Prototype the risky part
A focused prototype can reveal whether the data is usable, where responses fail, how much review is needed, and whether the workflow creates enough value to justify further investment.
We do not present a model demo as production readiness. The application still needs identity, permissions, logging, interface design, error handling, evaluation, and operational ownership.
Delivery path
Define the user, decision, data, risk, and measurable quality threshold.
Test representative examples, sources, failure modes, and human review needs.
Build the surrounding application, access controls, interfaces, and escalation path.
Track task quality, cost, latency, feedback, and changes after release.
PhaneLabs connects approved source material, review criteria, human decisions, and monitoring before an AI capability reaches routine use.
Practical questions
Not necessarily. The right approach may use an existing model, retrieval, deterministic rules, or a combination. The decision follows the task, data, risk, and cost.
Only after access, retention, provider, hosting, contractual, and jurisdictional requirements are understood. Sensitive data should never be assumed safe by default.
We define representative test cases and review criteria for the exact task. A general model benchmark is not a substitute for workflow-specific evaluation.
Bring the workflow, not the hype
Tell us what people do today, which information they use, what errors matter, and who remains accountable. That is enough to begin a useful conversation.